


I lead Federal.AI, building Decision APIs that turn fragmented operational data into evaluated, evidence-backed decisions - designed to run in air-gapped environments with explicit human authority.
Founder & CEO, Federal.AI · PhD in Artificial Intelligence · CISSP / ISSEP · Commercial pilot & CFI
Experiments · Field notes · Discuss a strategic engagement ↗
My perspective combines AI engineering, commercial aviation, and ownership of Blue Ridge Electric Service. Models, agents, optimization, data infrastructure, and simulation are components. The product is a better decision with inspectable evidence.
A conventional API returns data. A Decision API should return a decision object:
- Recommendation - what the system proposes.
- Evidence - the records and observations supporting it.
- Constraints - what must remain true.
- Alternatives - feasible options considered.
- Uncertainty - what the system does not know.
- Evaluation - which deterministic and model-based checks passed.
- Authority - who may approve or execute the action.
- Provenance - enough lineage to reconstruct why the decision was produced.
The design target is an AI system that can ingest fragmented operational evidence, reason over it, call deterministic solvers and tools where appropriate, and produce a decision artifact that can be tested before it is trusted.
Air-gapped by design. Local models, local retrieval, local evaluation, pinned artifacts, explicit dependencies, and graceful operation without cloud services are architectural requirements rather than deployment afterthoughts.
Original, reproducible experiments in model behavior, operational evidence, and data economics.
I publish the inputs, methods, raw outputs, and failure cases so another engineer can challenge the result.
| Experiment | What it tests | Evidence |
|---|---|---|
| NiFi diagnosis for GoldenAye | Can a local model distinguish a configuration concern from an unsupported claim about runtime behavior? | Public synthetic cases, a deterministic baseline, strict output grading, and recorded model outputs |
| Ingest economics | At the same byte budget, which sampling policy preserves useful diagnostic context? | 20 seeded trials, equal-volume comparisons, explicit cost assumptions, and reproducible charts |
Explore the experiments → · Methods and limitations
These are development experiments with synthetic data. The reports separate software checks, model performance, and business assumptions.
Decision quality, not chatbot quality. Evaluate whether a proposed decision is feasible, supported, useful, and appropriately bounded.
Evidence before eloquence. A fluent recommendation without provenance is a failed decision artifact.
Hybrid reasoning. Use language models for interpretation and tool selection; use deterministic code, constraint solvers, and rules where correctness can be computed.
Human authority as architecture. Approval binds to the exact proposed action and expected state, not to a vague conversational intent.
Whole-system evaluation. Models are one component. Data quality, retrieval, tool execution, optimization, evidence lineage, failure recovery, and reviewer effort all affect operational value.
| Field note | Practical question |
|---|---|
| Measure AI cost per useful outcome | When does reviewer effort erase the apparent savings? |
| Human approval is an architecture boundary | How do we ensure the reviewed action is the one that executes? |
| Evaluate the whole disconnected AI system | What evidence supports a claim that a workflow can operate offline? |
| Where AI creates operational value | Which decisions should we improve, and where should authority stop? |
All engineering field notes → · Speaking topics and bio →
A public aircraft-readiness demonstration that brings scattered evidence, a proposed decision, and human approval into one interface. Synthetic scenario.
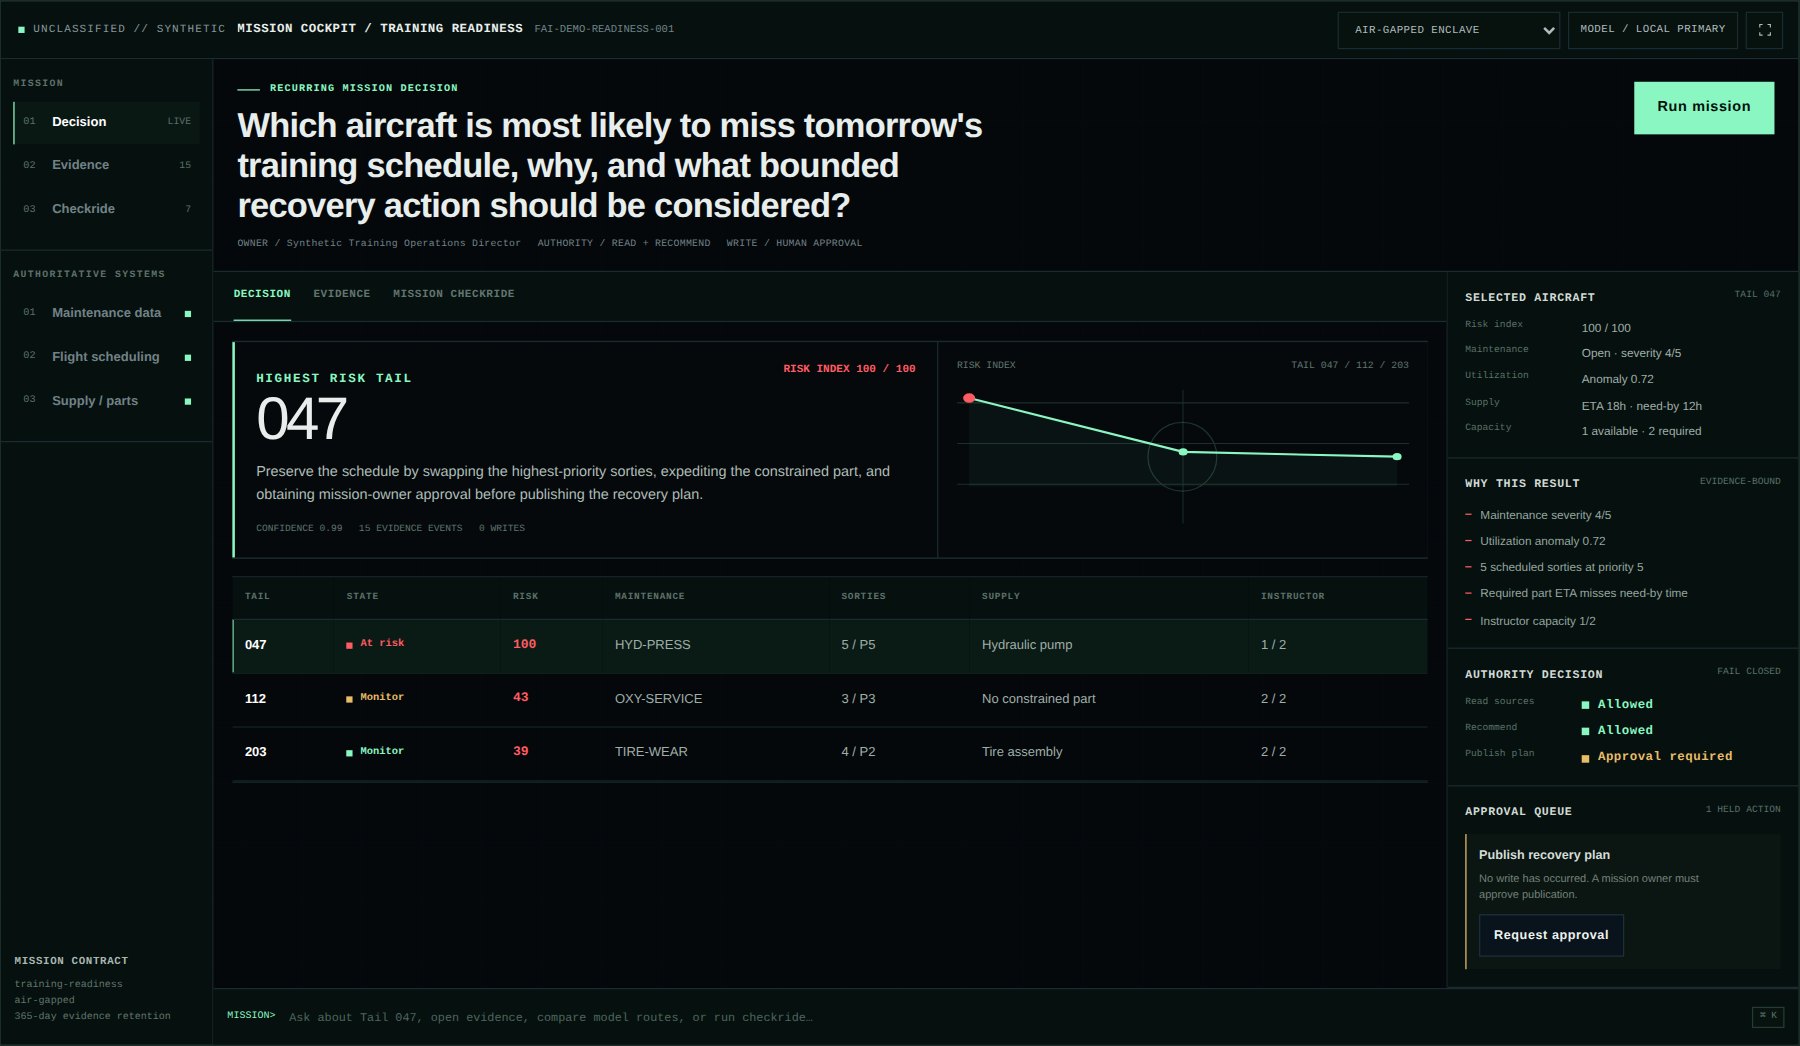
Explore the demo · Engineering brief
A private AI workspace for Apache NiFi flows: chat with flow evidence, inspect configuration, and compare ingest policies with deterministic replay. Built around local models and operator review; the pilot is under evaluation for disconnected deployment.
Explore GoldenAye · Flow-validation example · Run the validation tool
A pilot workspace for checklist prompts, phrase references, and debrief notes, developed with my daughter Lilli. AOPA covered our story in January 2026.
Launch No Brashers · Product brief
Four focused prototypes built on community projects, with upstream credit, runnable examples and 37 passing local tests across the additions.
| Project | My contribution | Upstream |
|---|---|---|
| Flow Doctor research | Early flow-inspection work supporting GoldenAye Flow Lab: evidence-linked inspection, HTML/JSON reports and an optional local Strands/Ollama explanation adapter. Model inference in this prototype is not yet validated. | Strands Harness SDK |
| Chalker | Aircraft scheduling proposals with maintenance conflicts, owner review, turnaround buffers and DST checks through a shared agent action. Headless; no bookings. | Builder.io Agent-Native |
| Motor Quote Workbench | Editable motor quote spreadsheet, specification screening and gross-margin pricing for industrial service workflows. Local browser app; no AI inference. | Univer |
| Federal.AI Preflight | Static AX manifest checks for artifact pinning, egress, references and offline assumptions. No deployment or accreditation claim. | Google AX |
Each repository separates the added domain logic from the original framework. Synthetic examples only; validation limits and quickstarts are documented.
| Product or business | Focus |
|---|---|
| CyberPlane | Aircraft maintenance records and evidence workflows. An aviation AI product in development. |
| LloydPilot.com | My aviation home: aircraft stories, interactive learning, and the curiosity behind the engineering. |
| Blue Ridge Electric Service | Electric motors, industrial service, and firsthand experience with equipment reliability and operating costs. |
A published app for Splunk Enterprise and Splunk Cloud. Built with my daughter Lilli, SPLap turns real telemetry into interactive analysis and hands-on SPL learning.
Explore the app · Get it on Splunkbase
Aviator Prompts: 38 prompts · Squadron Prompts · Nintendo DS training prototype
Tools I work with: Python · Apache NiFi · Splunk · SQL · local LLMs · RAG · evaluation · constraint optimization · MCP · simulation
I work with enterprise leaders, program owners, and prime partners on Decision APIs, air-gapped AI, data infrastructure, and operational assurance.
Start with a short brief: your organization and role, the recurring decision you want to improve, the fragmented evidence used today, the deployment environment, and how you currently determine whether the decision was correct.
Submit an engagement inquiry · Federal.AI · Speaking and technical briefings
Hero: AI-generated concept artwork. Product screenshots and synthetic demonstrations are identified separately. GoldenAye Flow Lab by Federal.ai is an independent project and is not affiliated with or endorsed by the Apache Software Foundation. Aviation resources are educational; verify outputs against current authoritative references.